Which AI assistant should you pay for?
Six assistants, three questions, and a shortlist of two profiles instead of a verdict. Nothing here has been used, trialled or tested by me: the comparisons below are each profile's own written judgement, and this page prints no prices of its own. If that sounds like a low bar for a buying decision, it is the highest one this site can honestly clear.
Three questions, in this order, before you compare model names
Most comparisons start with the model names and work backwards. This one starts with the shape of your work, because that is the part you can answer without a trial. The figure below is the whole method; the rest of this page is the evidence for each branch.
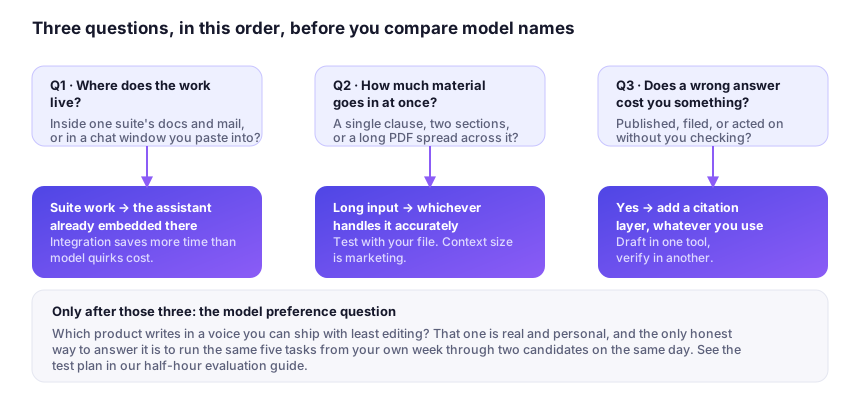
Q1 · Where does the work live?
Inside one suite's docs and mail, or in a chat window you paste into? If your day runs in Gmail, Docs and Drive, the assistant already embedded there has an advantage a chat window cannot copy: it reads the thread and the file without being handed them. Gemini's profile says to buy it for the plumbing, not the model; its first reason not to buy is that you are on Microsoft 365, where the assistant already in your suite does more for less friction. That is also the honest boundary of this page: we do not have a profile of the Microsoft 365 assistant, so this desk will not name one for that suite. If your work arrives as files you paste or upload, the suite advantage disappears and Q2 decides.
Q2 · How much material goes in at once?
A single clause, two sections, or a long PDF spread across it? Long input is a different job from twenty short tasks a day. Claude's profile is the one that says it will not dazzle you in a five-minute trial — it wins in week three, when you notice how little you had to rewrite — and it warns that context size is marketing: test with your file. ChatGPT's profile says nothing else covers as many tasks in one place. Neither page claims a measured accuracy comparison, because neither of us ran one.
Q3 · Does a wrong answer cost you something?
Published, filed, or acted on without you checking? Then the answer is not a different assistant; it is a second layer. Perplexity's profile calls it the verification layer, not the writing layer, and tells you to click at least one citation before you believe a number. ChatGPT's own verdict says never publish a fact it gave you without checking the source. Draft in one tool, verify in another — that sentence is the whole recommendation for anyone whose output leaves the room.
The outcomes, as a table
Every path below returns two profiles. The first is where to start; the second is the check. They are not a ranking of the two, and the order does not mean the first is better. If you take one thing from this page, take the pair, not the first name.
| Where the work lives | How much goes in at once | If a wrong answer costs you | Read these two first |
|---|---|---|---|
| In Google apps — Gmail, Docs, Drive | One long document at a time | Yes — it gets published, filed or sent | Gemini, then Perplexity |
| In Google apps — Gmail, Docs, Drive | One long document at a time | No — ten minutes | Gemini, then Claude |
| In Google apps — Gmail, Docs, Drive | Many short tasks a day | Yes — it gets published, filed or sent | Gemini, then Perplexity |
| In Google apps — Gmail, Docs, Drive | Many short tasks a day | No — ten minutes | Gemini, then ChatGPT |
| In a chat window I paste into | One long document at a time | Yes — it gets published, filed or sent | Claude, then Perplexity |
| In a chat window I paste into | One long document at a time | No — ten minutes | Claude, then ChatGPT |
| In a chat window I paste into | Many short tasks a day | Yes — it gets published, filed or sent | ChatGPT, then Perplexity |
| In a chat window I paste into | Many short tasks a day | No — ten minutes | ChatGPT, then Claude |
| On X, as it happens | — | — | Grok, then Perplexity |
| In code or a data pipeline | — | — | DeepSeek, then Claude |
| In Microsoft 365 | — | — | No pair. We have no profile of the suite assistant. |
Three moves summarise the branches: Suite work → the assistant already embedded there; Long input → whichever handles it accurately; Yes → add a citation layer, whatever you use. The figure's own notes are the reasons: Integration saves more time than model quirks cost. Test with your file. Context size is marketing. Draft in one tool, verify in another.
Two cases this funnel does not cover
The three questions assume the work is text you hand over. Two of the six profiles do not fit that shape, and pretending they did would produce a false answer.
Grok: you need to know what is being said right now
Grok's verdict is one sentence long in its own profile: "Buy it for one specific reason — live access to X — and nothing else." If that is your reason, start there and check it against Perplexity before you repeat it. If it is not, the profile's own warning applies: between the watermark rule and the moderation record, this is the wrong tool to have on your letterhead.
DeepSeek: the work is volume, not a chat
"Nobody should pay DeepSeek for a consumer subscription, because there is not one to pay." If your job is volume text work, the API and the open weights are the products to compare, and the decision is about hardware and data terms rather than a monthly plan.
Only after those three: the model preference question
Which product writes in a voice you can ship with least editing? That one is real and personal, and the only honest way to answer it is to run the same five tasks from your own week through two candidates on the same day. See the test plan in our half-hour evaluation guide.
What this page is not
It is not a ranking. No accuracy percentage, no star rating, no "best overall" — I have not run a controlled comparison, and a hand-made one would be theatre.
It is not a test. Nothing here has been used, trialled or tested by me. The evidence is each vendor's documentation and published pricing, read on their own pages, plus the written judgement on each profile.
It is not a price table. Price is the second question, not the first: the figure belongs on the profile, where it carries the month it was read and stops printing the check date once that month ages out. This page will not build a price table it cannot keep current.
It is not affiliate-driven. No affiliate links, no sponsored placement, no paid inclusion; outbound links are plain nofollow.
Half an hour, two candidates
The shortlist is only as good as the test you run on it. These four checks come from the profiles' own test lists, and they take about half an hour:
- Run the same five tasks from your own week through two candidates on the same day, and score each run on one question: how much editing did the output need before I'd send it out?
- Give it a task with a hard constraint (word limit, format, audience) and count how many constraints it silently drops.
- Ask a factual question you already know the answer to, then ask it to cite sources. Note whether it invents anything.
- Ask a question with a number in it that you can verify independently, then open the cited source and check the number appears where it claims.
Keep reading
- ChatGPT, Claude, Gemini, Perplexity, Grok and DeepSeek — the six profiles this page draws on.
- How to evaluate an AI tool before you pay for it — the half-hour test behind the checks above.
- The meeting-notes decision desk — the same shape, applied to one job.
- Audit what you already pay — the 30-day checklist for a subscription you have.